
For more than two decades, the web operated on an unspoken economic treaty: search engines crawl your pages for free, and in return, they send qualified human visitors back to your domain. This reciprocal contract fueled the entire organic search industry, digital publishing, and inbound marketing.
That treaty has broken down. Today, autonomous artificial intelligence agents and foundational LLM scrapers consume petabytes of proprietary website text, documentation, and original research—not to direct users to your website, but to synthesize complete answers directly inside chat boxes and zero-click answer engines.
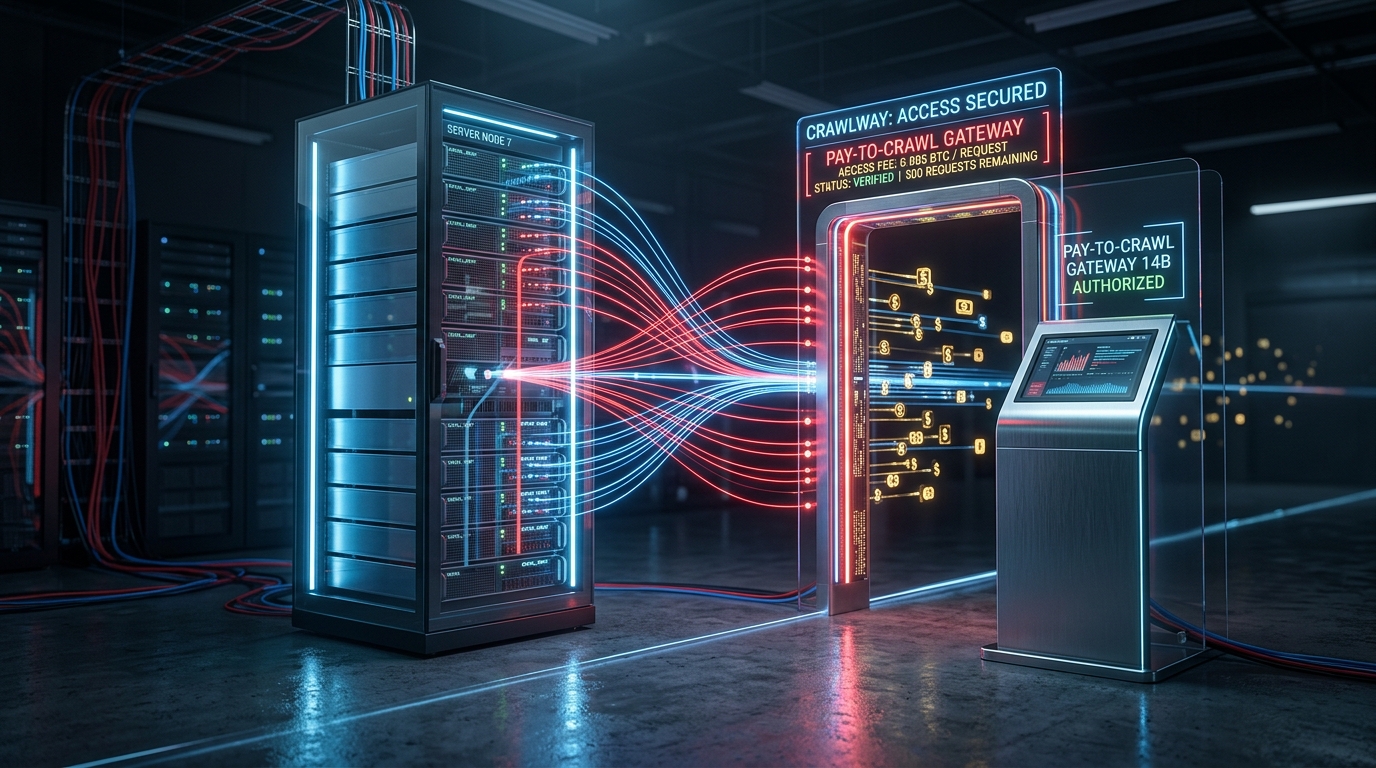
The response from publishers is swift: the rise of Pay-to-Crawl. Website owners are implementing cryptographic barriers, Cloudflare bot tollbooths, and micro-billing APIs that charge AI companies per request. But how does this seismic shift alter traditional technical SEO, organic visibility, and the future of LLM pre-training?
1. Decoupling Discovery From Data Extraction
In traditional search, crawling was synonymous with discovery. If Googlebot couldn’t access your code, your business didn't exist in Google Search. Today, website administrators are forced to distinguish between two completely different types of bot activity:
The Two Classes of Web Crawlers
- Discovery Bots (Search Crawlers): Crawlers like Googlebot or Bingbot that index web pages to populate organic SERP listings, direct citations, and local Map Packs, providing traffic back to the source.
- Extraction Bots (Training & Synthesis Scrapers): Scrapers like GPTBot, ClaudeBot, and CCBot that scrape millions of pages strictly to train offline foundational models or summarize articles without user referral clicks.
Pay-to-crawl architectures allow publishers to maintain public indexation on search engines while blocking or charging extraction bots. For digital strategists, mastering this distinction is at the heart of modern AI Search Optimization (GEO).
2. Comparison: The Old Web Contract vs. The Pay-to-Crawl Ecosystem
The transition from an open, free-scraping internet to a monetized crawler ecosystem fundamentally changes publishing revenue models:
| Dimension | Traditional SEO Era (Pre-2024) | Pay-to-Crawl Era (2026+) |
|---|---|---|
| Access Rule | Free crawling via standard robots.txt | Tokenized API gateways, Tollbit, Cloudflare Bot Tolls |
| Primary Currency | Referral clicks & ad impressions | Per-scrape micro-fees, syndicate licenses & GEO citations |
| Publisher Risk | Algorithm penalties & ranking drops | Content cannibalization & complete zero-click answer loss |
| AI Training Impact | Infinite free high-quality web datasets | Synthetic data collapse & prohibitive data licensing costs |
3. The Impact on AI Model Training: The Threat of Model Collapse
When authoritative media conglomerates, niche industry publications, and technical forums (like Reddit, Axel Springer, and Stack Overflow) put their data behind paid API barriers, AI labs face an existential crisis: data starvation.
If foundational models cannot freely scrape fresh human insights, they are forced to train on synthetic AI-generated content. Research from Cambridge and Oxford has proven that training models on recursive synthetic text inevitably leads to "model collapse"—where LLMs degrade in reasoning, hallucinate uncontrollably, and produce gibberish. As a result, authentic human-written content built with authentic E-E-A-T signals becomes exponentially more valuable.
4. What This Means for Content Strategy & SEO in 2026
As a business owner or marketing executive, how should your brand adapt to pay-to-crawl dynamics?
- Audit Your
robots.txtand WAF Rules: Ensure you are not accidentally blocking bots that drive citations in Google AI Overviews and ChatGPT Search while keeping your infrastructure shielded from aggressive rogue scrapers. - Focus on Commercial Buyer Intent: Informational trivia content is easily synthesized by AI answers with zero click-through. Prioritize commercial, bottom-of-funnel queries mapped out in our Content SEO Strategy framework.
- Deploy Entity & Schema Markup: Make your brand unmistakable to search engines by deploying structured On-Page SEO and entity schemas so AI models cite your business even if you restrict raw scraping.
Frequently Asked Questions
What is the pay-to-crawl model?
Pay-to-crawl is an internet architecture where website publishers enforce per-request micropayments or cryptographic licensing tokens before automated AI scrapers and web robots can index or extract their content.
How does pay-to-crawl affect traditional search rankings?
Traditional search engine crawlers that return organic referral traffic (like Googlebot) remain whitelisted for free. The paywall specifically targets offline LLM training bots that consume server bandwidth without returning user visits.
Should my company implement a pay-to-crawl gate?
If you run a media publication, proprietary research hub, or large forum, licensing your data is highly profitable. However, if your primary goal is lead generation and local sales, remaining open for answer engine citations (AEO) yields far greater customer acquisition returns.
Shekhar Samanta
Founder & Head of SEO at SpreadOrbit. Specializing in advanced technical SEO architectures, AI search optimization (GEO), and enterprise search gravity pipelines. Connect directly via Founder Profile.
Optimize Your Website for the AI Search Era
Don’t let your traffic disappear into zero-click answer summaries. Discover how SpreadOrbit optimizes your technical entity footprint to capture search citations that convert.