
The transition from static HTML crawling to real-time LLM inference has broken the traditional web monetization model. In 2026, web infrastructure engineers and digital strategists are witnessing the rollout of automated, programmatic Pay-to-Crawl architectures.
No longer confined to closed-door corporate negotiations between media moguls and AI founders, pay-to-crawl has matured into turn-key edge protocols, standardized HTTP headers, and decentralized data clearinghouses. In this architectural deep-dive, we examine the four dominant pay-to-crawl models operating in 2026 and how they intersect with Technical SEO.
1. The 4 Prevailing Pay-to-Crawl Models in 2026
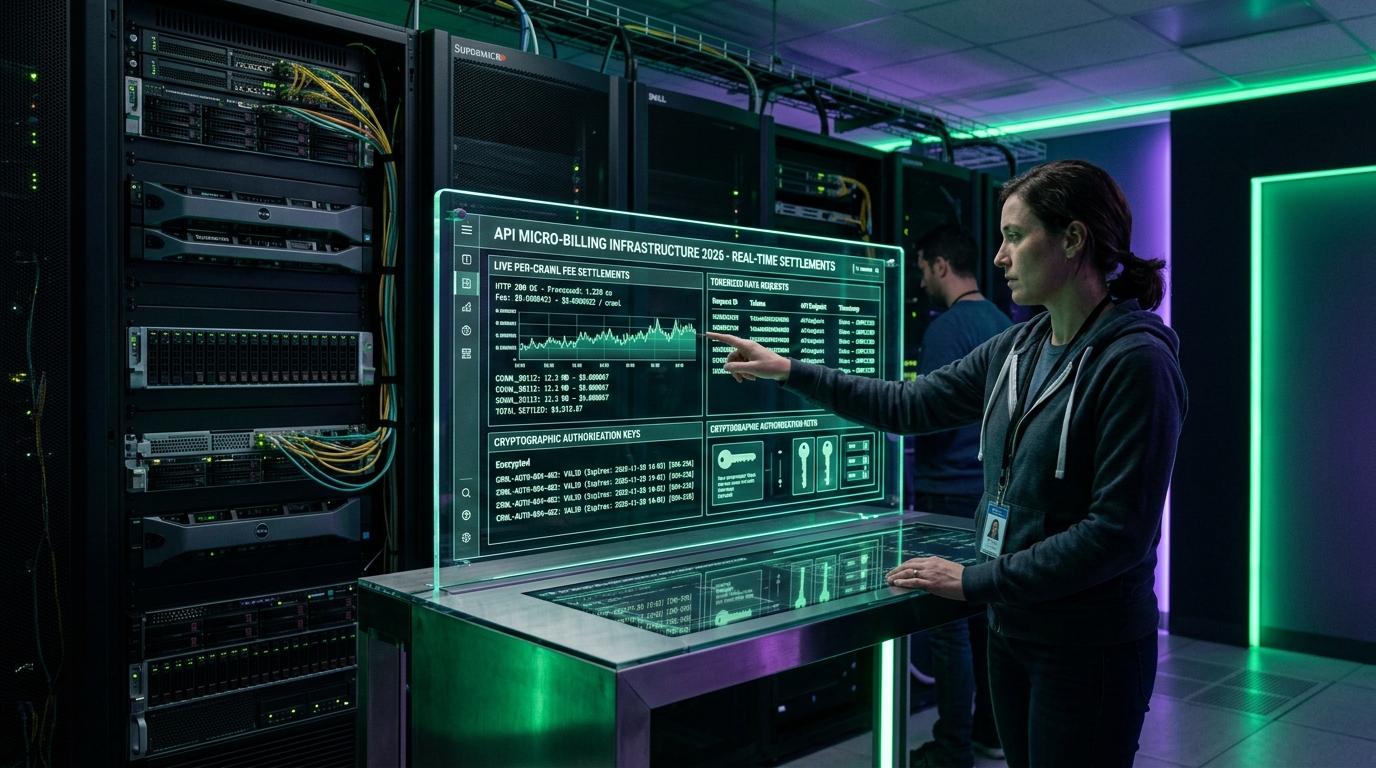
1. Metered Edge Micro-Billing
Most ScalablePlatforms like Tollbit and Cloudflare Bot Management act as intermediary tollgates. When an AI bot hits an endpoint, the edge server verifies a pre-funded credit balance or authorization token.
2. Syndicated Bulk Corpus Licenses
Enterprise TierLarge platforms negotiate annual recurring agreements granting raw database dumps or private vector pipelines for offline pre-training runs (e.g., Reddit & OpenAI/Google).
3. Real-Time RAG API Endpoints
High AccuracyInstead of scraping bloated HTML with CSS and scripts, websites serve pristine, pre-embedded Markdown/JSON over authenticated REST or GraphQL APIs optimized for Retrieval-Augmented Generation.
4. Hybrid SEO-Exchange Model
Hybrid CitationCrawlers are granted free data access on the strict contractual guarantee that any synthesis displayed to an end-user must feature an authoritative, prominent backlink and brand citation.
2. The Technical Infrastructure: How an HTTP 402 Flow Operates
When an AI bot requests a page on a pay-to-crawl enabled domain, modern CDN workers execute the following sequence:
// Example Edge Worker Bot Gateway
addEventListener('fetch', event => {
  const userAgent = event.request.headers.get('user-agent') || '';
  const isSearchEngine = /Googlebot|Bingbot/i.test(userAgent);
  const isAITrainingBot = /GPTBot|ClaudeBot|CCBot|Bytespider/i.test(userAgent);

  if (isSearchEngine) {
    return fetch(event.request); // Free organic search indexation
  }

  if (isAITrainingBot) {
    const authHeader = event.request.headers.get('Authorization');
    if (!authHeader || !verifyTollToken(authHeader)) {
      return new Response(JSON.stringify({
        error: "HTTP 402 Payment Required",
        message: "This domain requires authenticated micro-licensing. Visit tollbit.com/spreadorbit"
      }), { status: 402, headers: { 'Content-Type': 'application/json' } });
    }
  }

  return fetch(event.request);
});
This ensures that your search engine visibility remains completely untouched while commercial scrapers are filtered into monetization tunnels.
3. What This Means for Your SEO Strategy in 2026
As the pay-to-crawl paradigm matures, search ranking algorithms increasingly emphasize first-party brand authority and entity verification.
Google’s Helpful Content and core algorithm updates reward original data that cannot be scraped or simulated. By focusing on proprietary case studies, authentic customer stories, and structured entity graphs (via our AI Search Optimization), your business establishes unbeatable topical gravity.
Frequently Asked Questions
What are the main Pay-to-Crawl models in 2026?
The primary models include per-request edge micro-billing (Tollbit, Cloudflare), annual bulk corpus licensing agreements, structured RAG API endpoints, and citation-guaranteed hybrid search models.
What is the average cost per crawl for AI bots?
Rates typically range between $0.002 and $0.05 per document. Pricing fluctuates based on data freshness, niche domain authority, and clean semantic formatting.
How do publishers implement pay-to-crawl technically?
Publishers deploy edge proxy workers (Cloudflare, Fastly) or use specialized SDKs. The edge layer inspects crawler headers, checks authorization balances, and returns HTTP 402 if unauthenticated.
Shekhar Samanta
Founder & Head of SEO at SpreadOrbit. Architecting advanced technical SEO solutions, edge caching strategies, and enterprise search gravity. Connect on our Founder Page.
Future-Proof Your Technical SEO Architecture
Prepare your digital infrastructure for the next generation of search engines, AI agents, and crawler monetization. Partner with SpreadOrbit today.