
Data is the crude oil of the 21st century—and the internet's wells are running dry.
Between 2020 and 2024, artificial intelligence labs trained their models on an open, unguarded web. They scraped Wikipedia, Reddit, GitHub, local news portals, academic whitepapers, and billions of independent blogs without paying a single dollar. That free lunch is officially over.
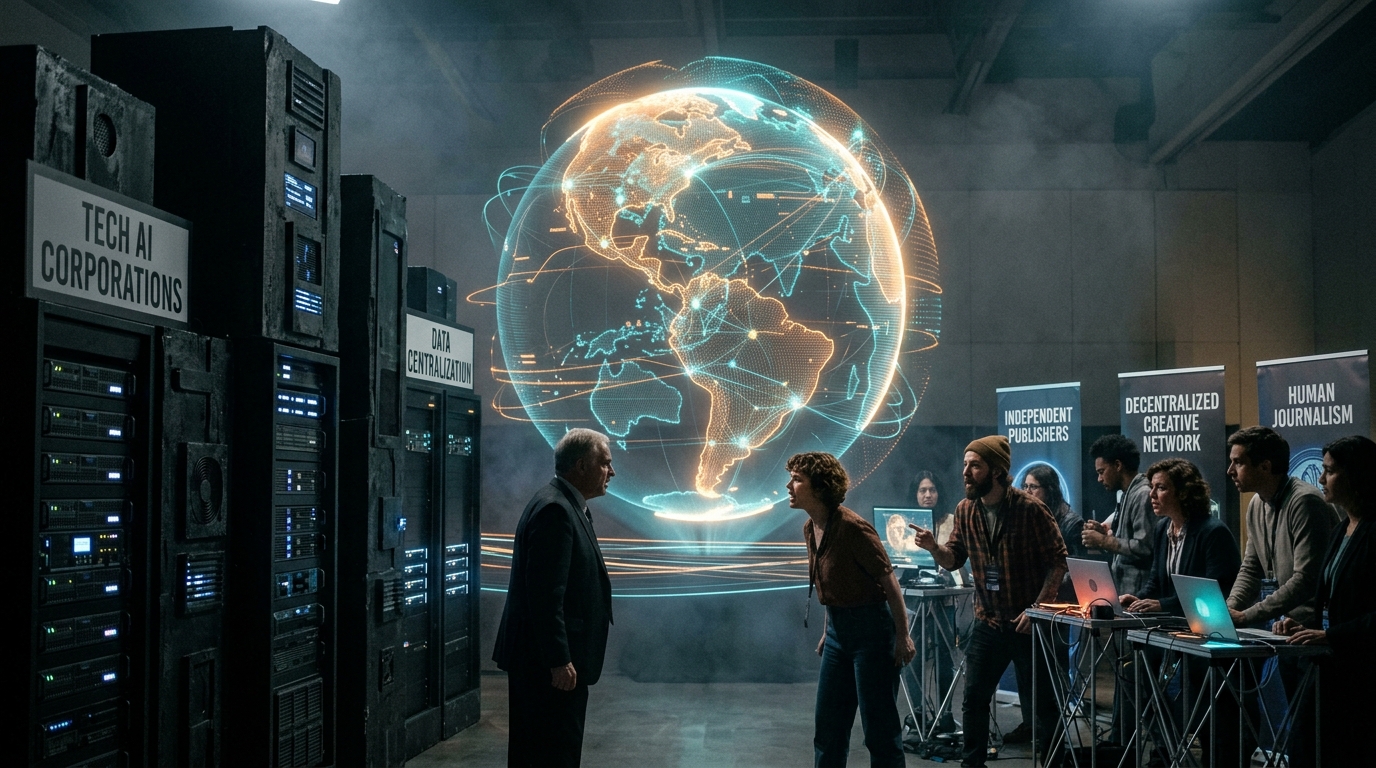
Today, a full-scale rebellion is underway. Publishers are barring their doors, tech giants are signing secret multi-million dollar data licensing agreements, and the very fabric of open search indexing is fracturing. Here is an inside look at the battle between websites and AI—and who stands to win.
1. The Rise of Crawler Boycotts
According to recent telemetry from Cloudflare and Reuters Institute, over 48% of the world’s top 1,000 websites now explicitly block AI training crawlers. In news and media, that number exceeds 75%.
Publishers realized that allowing crawlers to freely scrape their content was commercial suicide:
- Traffic Decapitation: Google AI Overviews and ChatGPT summaries reduce organic click-through rates by an estimated 35% to 60% on informational queries.
- Uncompensated Infrastructure Costs: Scraper clusters generate massive CPU spikes and gigabytes of egress bandwidth, costing publishers tens of thousands of dollars in hosting bills.
- Direct Market Cannibalization: The scraped content is used to build competing answer services that render the original creator irrelevant.
2. The Data Scarcity Wall: Why AI Labs Are Desperate
Leading research labs (Epoch AI) have estimated that high-quality, human-generated public text data on the web will be completely exhausted within the next 18 months. Frontier models have already read virtually every public English book, article, and codebase ever uploaded.
To keep improving frontier models, AI labs require two things:
1. Real-Time Human Data
Current news, market shifts, consumer sentiment, and freshly published expertise that keeps models relevant today.
2. Verified E-E-A-T Depth
First-hand experience and authentic clinical, technical, or legal conclusions that cannot be fabricated by AI text spinners.
Because synthetic data leads to model collapse, AI corporations have no choice: they must pay for access or negotiate private data syndication pipelines. Deals with Reddit ($60M/year), Stack Overflow, and News Corp have set the market precedent.
3. The Two-Tier Internet: Paywalled Data vs. Public Search
The battle for data is creating a fractured, two-tier web:
- Tier 1 (The Gated Garden): High-value journalism, proprietary forums, and enterprise data hidden behind paywalls, private APIs, and paid crawl gateways.
- Tier 2 (The Public Commons): Commercial websites, local businesses, and brand assets that deliberately remain open to capture customer inquiries and dominate answer engine citations.
For brands and local businesses, Tier 2 represents an unprecedented opportunity. As legacy publishers retreat behind paywalls, businesses that invest in authentic Content Strategy and topical authority will own the public answers that prospective buyers rely on.
Frequently Asked Questions
Why are websites blocking AI bots from scraping data?
Because AI summaries satisfy user queries directly inside chat interfaces, stealing referral traffic, ad impressions, and customer leads while consuming publisher server bandwidth for free.
What percentage of top websites block AI bots?
Over 48% of the top 1,000 global domains and more than 75% of leading news media organizations currently block major AI training scrapers like GPTBot and CCBot.
Can AI models survive without scraping the open web?
No. Training models on recursive synthetic AI text causes severe cognitive degradation and hallucinations known as model collapse. Fresh human insight remains the fundamental fuel of generative intelligence.
Shekhar Samanta
Founder & Head of SEO at SpreadOrbit. Strategizing enterprise organic growth, AI search adaptation, and authoritative entity networks. Connect via Shekhar’s Profile.
Own Your Market’s Search Authority
In the battle for search visibility, authority is the only currency that matters. Partner with SpreadOrbit to build an organic search pipeline that outranks legacy rivals.